Let me paint you a scene that I’ve lived more times than I’d like to admit.
The sprint is done. Testing is done. The team signs off. The release goes out on a Friday afternoon (always a Friday, for some reason). And then, sometime between Saturday morning and Monday standup, a user finds something. A bug. Something that breaks a real workflow. Something that was absolutely, definitely, supposed to have been caught.
That moment, that specific sinking feeling has a name in QA. It’s called defect leakage.
And if you’ve never formally tracked it, I’d argue you’re flying blind on one of the most important signals your testing process produces.
So what exactly is defect leakage?
The definition is straightforward: defect leakage occurs when a bug that existed during testing makes it all the way to production or a later phase of the release cycle —without being caught.
You had the code. You had the test environment. You had the time. The defect was there. And it still got through.
Imagine you’re testing an e-commerce checkout. Your team runs 200 test cases, covering the happy path, edge cases, and payment failures. The build goes to production. Three days later, a customer reports that applying a discount code and changing their delivery address in the same session wipes out their cart. Silently. No error. Just gone. That’s a defect leakage. It existed
when you were testing. It wasn’t caught. The user found it instead.
Now, some people hear “defect leakage” and immediately get defensive. “We can’t catch everything.” And honestly? That’s true. No QA process catches 100% of bugs. But defect leakage isn’t about perfection; it’s about understanding what your testing process is actually doing.
Why this metric matters more than your test pass rate
Here’s a thing I’ve seen happen in a lot of teams: the test pass rate looks great. 95%. 98%. Green dashboards everywhere. Leadership is happy. QA is happy. And then production keeps catching fire.
The problem is that a high pass rate just tells you that the tests you wrote passed. It says nothing about what you didn’t test. Defect leakage tells you something entirely different; it tells you about the gap between what you tested and what reality threw at you.
The formula is simple: take the number of defects found in production (or a later phase), divide by the total defects found across all phases, and multiply by 100. A lower percentage means more defects were caught before reaching users. A higher percentage means your testing net has holes.
That gap is where the real QA work lives. And unless you’re measuring it, you won’t know how big it is or where it comes from.
The most common reasons defects leak through
In my experience, defect leakage rarely comes from laziness or carelessness. It usually comes from a few structural problems that quietly build up over time.
Test coverage that looks complete but isn’t. We often design tests around how the feature should work, not around how users will actually use it. The combination of two valid actions that creates an invalid state? That’s not in most test plans. That’s where bugs live.
Regression blind spots. A change in one area breaks something in another area that nobody connected in their head. This is especially common in mature, complex systems where the team has half-forgotten what touches what.
Environmental differences. Something works fine in staging. It breaks in production because the data, load, and configuration are slightly different. Environment parity issues are a classic source of leakage that gets blamed on QA, but often isn’t purely a testing problem.
Time pressure. This one’s uncomfortable but real. When a release is being pushed out fast, testing gets compressed. Corners get cut. Risk gets accepted informally, without anyone really naming it. And then the risk materializes in production.
How to actually use defect leakage data
The number itself isn’t the point. What you do with it is.
When I track defect leakage properly, the first thing I want to know is: where did this bug come from, and why didn’t we catch it? That retrospective question is worth more than the metric itself. Was it a missing test case? An assumption we made about user behavior that turned out to be wrong? A dependency we didn’t know about?
Over time, patterns emerge. It may be concentrated in one feature area. Maybe it consistently shows up after integrations with a specific third-party service. It may spike after releases with compressed timelines. That’s intelligence. That’s where you direct your attention next.
What good looks like
One team I worked with had persistent leakage around their notification system, bugs kept reaching users even though the feature was “well-tested.” When we dug into it, the issue was that tests were validating that notifications were sent, but not validating what happened when the user’s preference settings interacted with different notification types. A focused expansion of coverage in that specific area dropped their notification-related leakage to near zero over two sprints.
A system that actually worked — and that you can steal
I want to share something concrete from a team I was part of, because I think it’s one of the most practical approaches to defect leakage I’ve seen in action. It wasn’t complicated. It didn’t require a big process overhaul. But it was consistent, and that’s what made it work.
Idea worth borrowing
The weekly production bug review — with Jira doing the heavy lifting
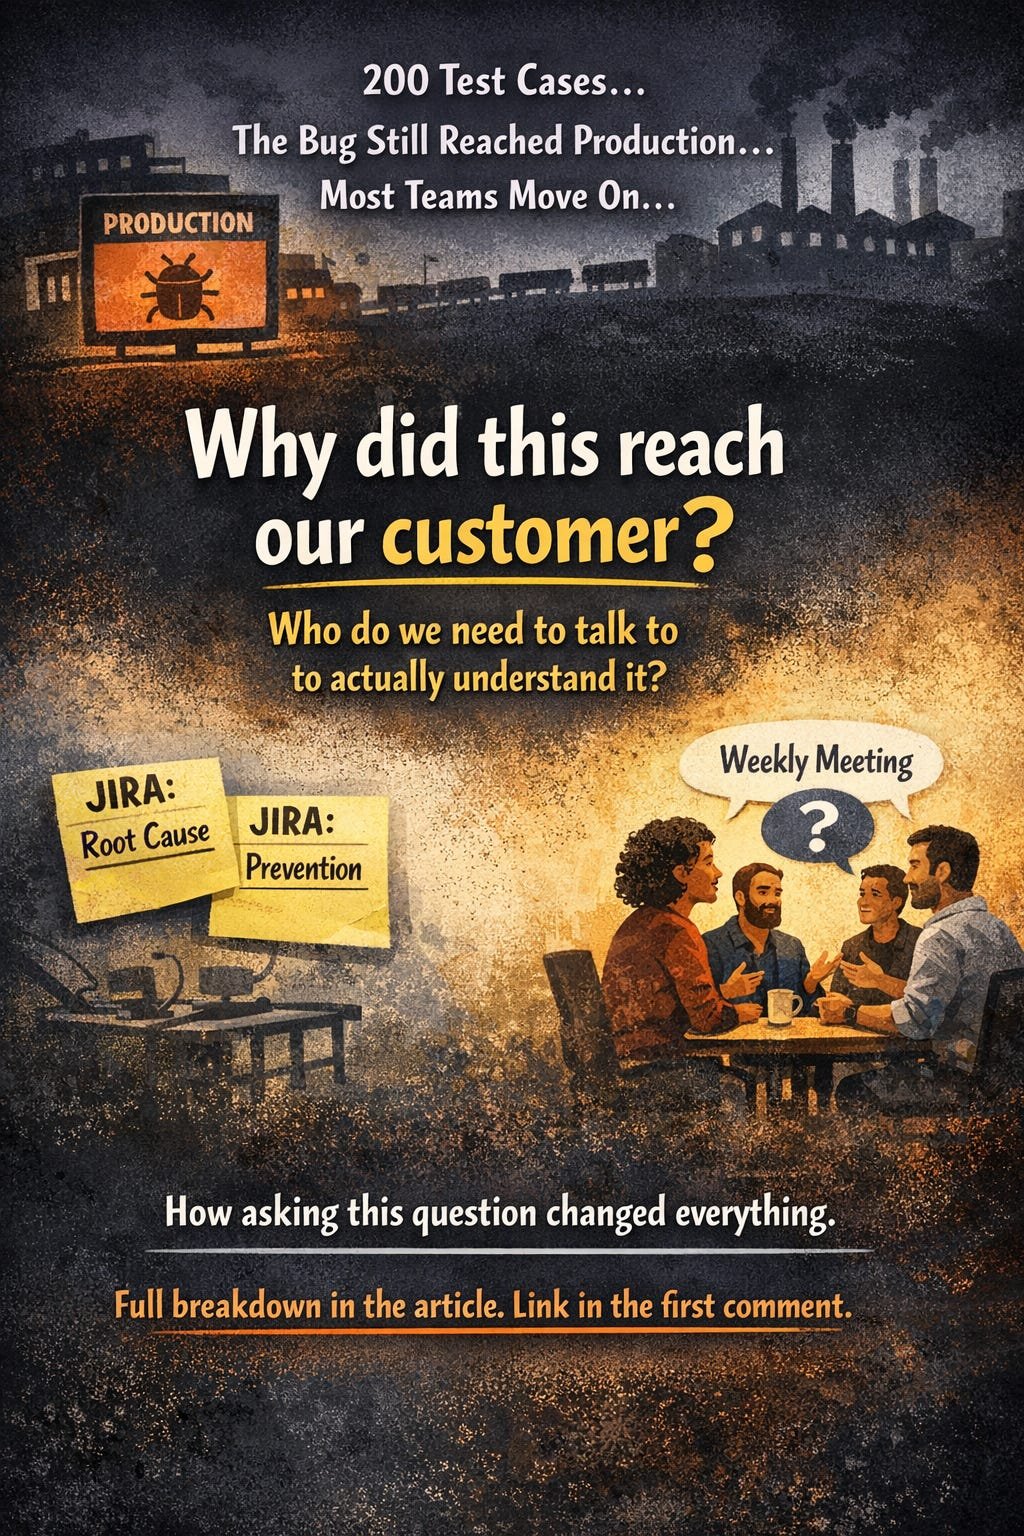
Our QA manager set up custom fields directly in Jira for every bug that reached production. The fields weren’t there to generate reports for leadership they were there to force a structured conversation. Specifically, each production bug ticket required answers to three things: why it was missed, what QA should do about it, and who else needs to be involved to fully understand it.
That last one matters more than it sounds. A production bug doesn’t always have a QA answer. Sometimes the only way to understand why a customer is seeing something is to sit down with a developer and ask what changed under the hood. Or with a project manager to understand what requirements shifted late in the sprint. Or with support to understand exactly what the customer was doing when it broke. The Jira fields created a paper trail that made those conversations happen, rather than letting the bug quietly get closed and forgotten.
The weekly meeting
Every week, the entire QA team met to review production bugs together. The ritual was simple, but the discipline around it was serious:
-
Zero production bugs that week? The meeting still happened. The team used the time to review the QA backlog, specifically assessing whether existing bugs required new regression tests or whether new test cases should be written based on recent releases. A quiet week was an opportunity to strengthen coverage, not an excuse to skip the conversation.
-
Production bugs found? The team walked through each one together. Why did it leak? Was the test case missing entirely? Did we test the wrong thing? Was it a known risk that got accepted under time pressure? And critically, do we need to pull in dev, the PM, or anyone else to get the full picture? Because sometimes QA alone can’t answer why a customer saw what they saw. That’s not a failure; that’s just how complex software works. The failure is not asking.
The culture that made it work
What made this system effective wasn’t the Jira fields or even the weekly cadence. It was what happened inside the room. Nobody was blamed. The question was never “whose fault is this?” It was always “what does our process need to learn from this?” and, just as importantly, “who do we need to talk to in order to actually understand this?”
That distinction sounds small. In practice, it’s everything. It’s the only way people tell the truth about what happened. And it’s the only way a production bug becomes something useful instead of something everyone just wants to move past.
When QA, dev, and the PM are sitting together looking at the same Jira ticket, asking the same question why did this reach our customer? the answer is almost always richer and more honest than anything QA could have figured out alone.
Why is it worth the hour?
If your team isn’t doing something like this, I’d genuinely recommend starting here before investing in any tooling or automation. The meeting costs an hour a week. The return cleaner releases, a smarter regression suite, a team that’s actually learning from production, and cross-functional conversations that surface things no single role would catch alone compound over time in ways that are hard to overstate.
A word on what defect leakage is not
It’s not a stick to beat QA with.
I’ve seen defect leakage metrics get weaponized and turned into a performance measure that makes QA engineers defensive and risk-averse. That’s exactly backward. If people are afraid to report or acknowledge production defects because it’ll reflect badly on testing, you lose the signal entirely. You need a culture where leaked data is treated as information, not blame.
It’s also not a complete picture of testing quality on its own. A team that ships tiny, well-scoped features might have low leakage simply because there’s less surface area for bugs to hide. A team tackling complex, high-risk migrations might have higher leakage while still doing excellent work. Context always matters.
Why does this become even more important as AI enters the picture?
I’ll be honest, this is something I think about a lot right now.
As AI-generated code becomes more common, the nature of defects is changing. AI can write functional-looking code that passes unit tests and fails in integration. It can produce edge cases that nobody explicitly thought about, because nobody explicitly wrote that code; a model interpolated it from patterns. The kinds of bugs that leak through are going to get more subtle, more contextual, harder to anticipate.
That means defect leakage tracking and the retrospective thinking that comes with it becomes more valuable, not less. Understanding what your testing missed and systematically closing those gaps is the kind of work that doesn’t get automated away. It requires understanding what “correct” actually means in your specific context. That’s still a human judgment. That’s still QA work.
The bottom line
Defect leakage is one of the clearest signals your testing process generates. It tells you, in concrete terms, what got through the net. Not hypothetically, actually.
If you’re not tracking it, start small. Pick the last three releases. Look at the production bugs. Trace them back. Ask whether they were testable during the testing phase. That exercise alone will tell you something useful.
And if you want a ready-made ritual to build around it, the weekly review I described above is as good a starting point as any. Zero bugs? Use the time to strengthen your test suite. Bugs found? Use them to teach your process something. Either way, the hour is never wasted.